Open AI performance, agents that go from code to production on their own and a behind-the-scenes look at delivering real-time voice AI.

Multi-token prediction drafters make Gemma 4 up to 3 times faster
Google released multi-token prediction drafters for the Gemma 4 family, which has passed 60 million downloads. The technique, called speculative decoding, uses a light model to predict several tokens ahead, which the main model checks at once, using compute that would sit idle. According to Google, this gives up to 3 times more speed with no loss of quality, in tools such as LiteRT-LM, MLX, Transformers and vLLM.
Faster answers on the same hardware improve assistants and cut the cost of serving your own models. Those running Gemma locally or on servers can turn on the drafters without changing models.
How Dexpert helps: Artificial Intelligence
Agents can now create accounts, register domains and deploy apps on Cloudflare
Cloudflare now lets coding agents, on behalf of the user, create an account, start a paid plan, register a domain and get a token to deploy the app right away. The flow uses a protocol built with Stripe as part of Stripe Projects, and the person only steps in to grant permissions and accept the terms of service. The company also offers $100,000 in credits to startups incorporated through Stripe Atlas.
The path from prototype to production gets much shorter for MVPs and new projects. Still, define who approves the spending and access agents request on the company's behalf.
How Dexpert helps: Cloud & ServerlessSources
- The Cloudflare Blog: Agents can now create Cloudflare accounts, buy domains, and deploy
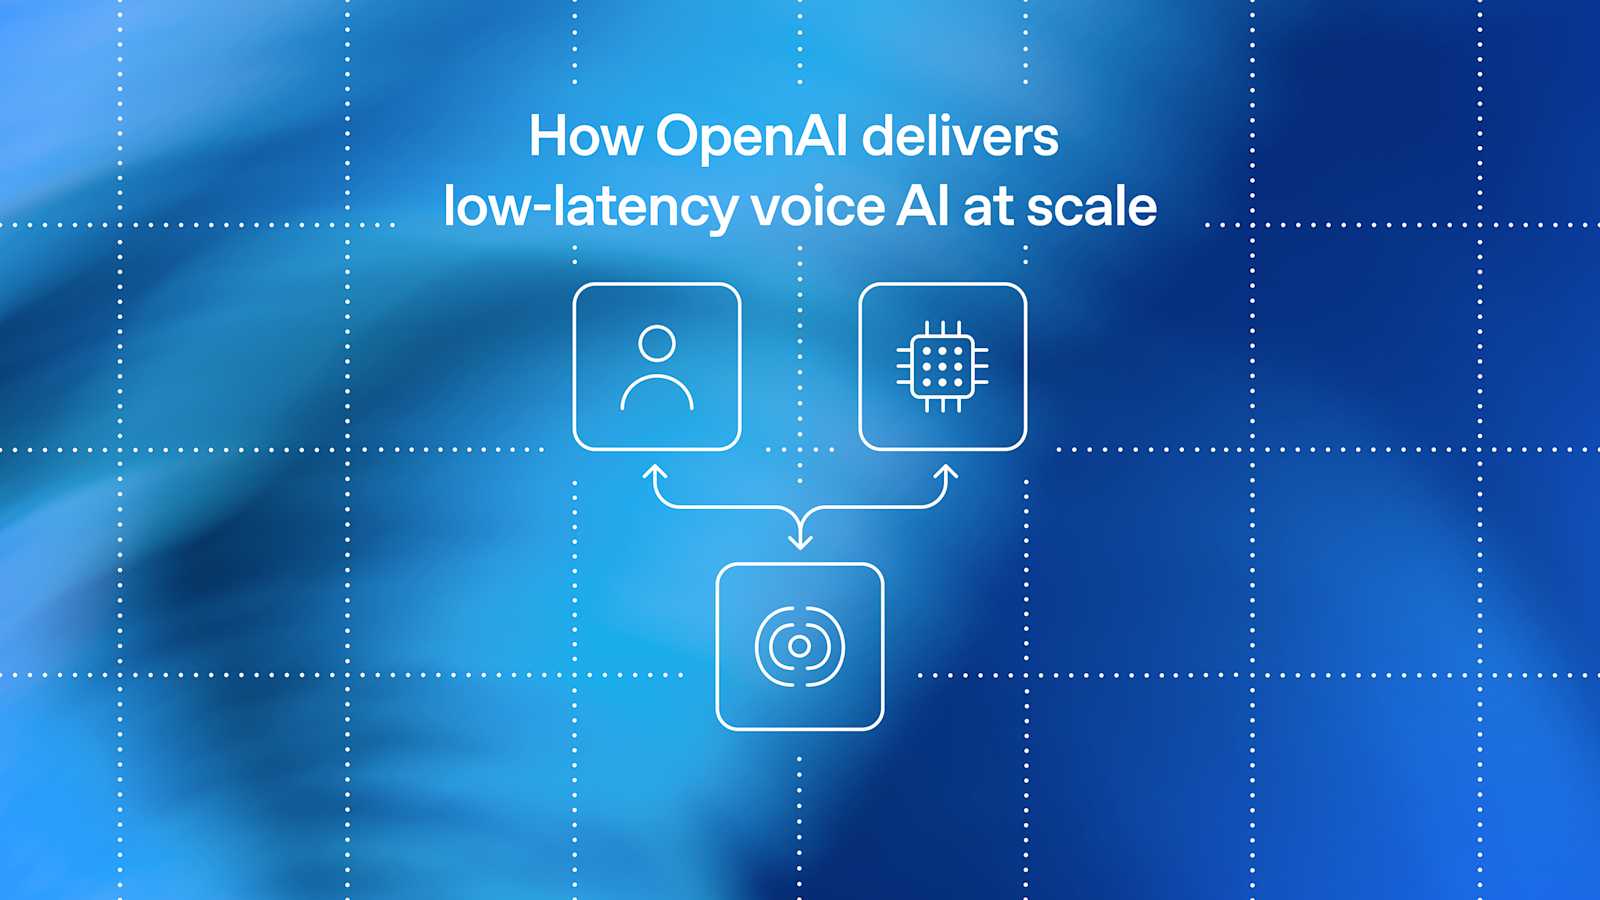
How OpenAI delivers low-latency voice AI to 900 million users
OpenAI explained how it reworked its WebRTC infrastructure for ChatGPT voice and the Realtime API, which serve more than 900 million weekly users. The one-port-per-session model did not fit Kubernetes, and sessions need to keep the same owner to work. The solution was to split a relay from a transceiver, keeping standard WebRTC for clients and changing only how packets are routed internally, to connect fast and keep latency low and stable.
For voice assistants, phone support or apps with real-time conversation, network latency matters as much as the model. The case shows that using open standards such as WebRTC and taking care of routing is the path to natural conversation.
How Dexpert helps: Backend & APIsSources
Want to put one of these to work in your company?
Dexpert builds custom systems, apps, integrations and AI solutions. Tell us what you need and get an estimate, or take the free digital maturity assessment.